YEAR
TIMELINE
TYPE
(Master’s graduation project)
SIMON FRASER UNIVERSITY, SIAT
TEAM
NT
ÖY
GR
(Solo project)
SUPERVISED BY DR. ÖZGE NILAY YALÇIN & DR. GILLIAN RUSSELL
KEYWORDS
GENERATIVE AI
GENERATIVE UI
DESIGN FUTURES
DESIGN FICTION
The Context
What could our homescreens look like in the future with generative AI?
The question started as a frustration and became my Master’s thesis at Simon Fraser University, a futures-first experiment in what home screens could become with generative AI.
Genie is a reimagining of the home screen where multi-agent AI systems dynamically generate adaptive interfaces in direct response to user intent.
What I set out to build
I wanted to make something you could actually use, and something you could imagine living with. So the project split in two:
PROBABLE FUTURE
A working proof-of-concept
A voice-driven prototype that interprets intent and generates a real UI with today’s technology.
PREFERRED FUTURE
A diegetic prototype video
A Design Fiction artefact showing the same idea once the technology catches up.
the problem
is this the best we can do?
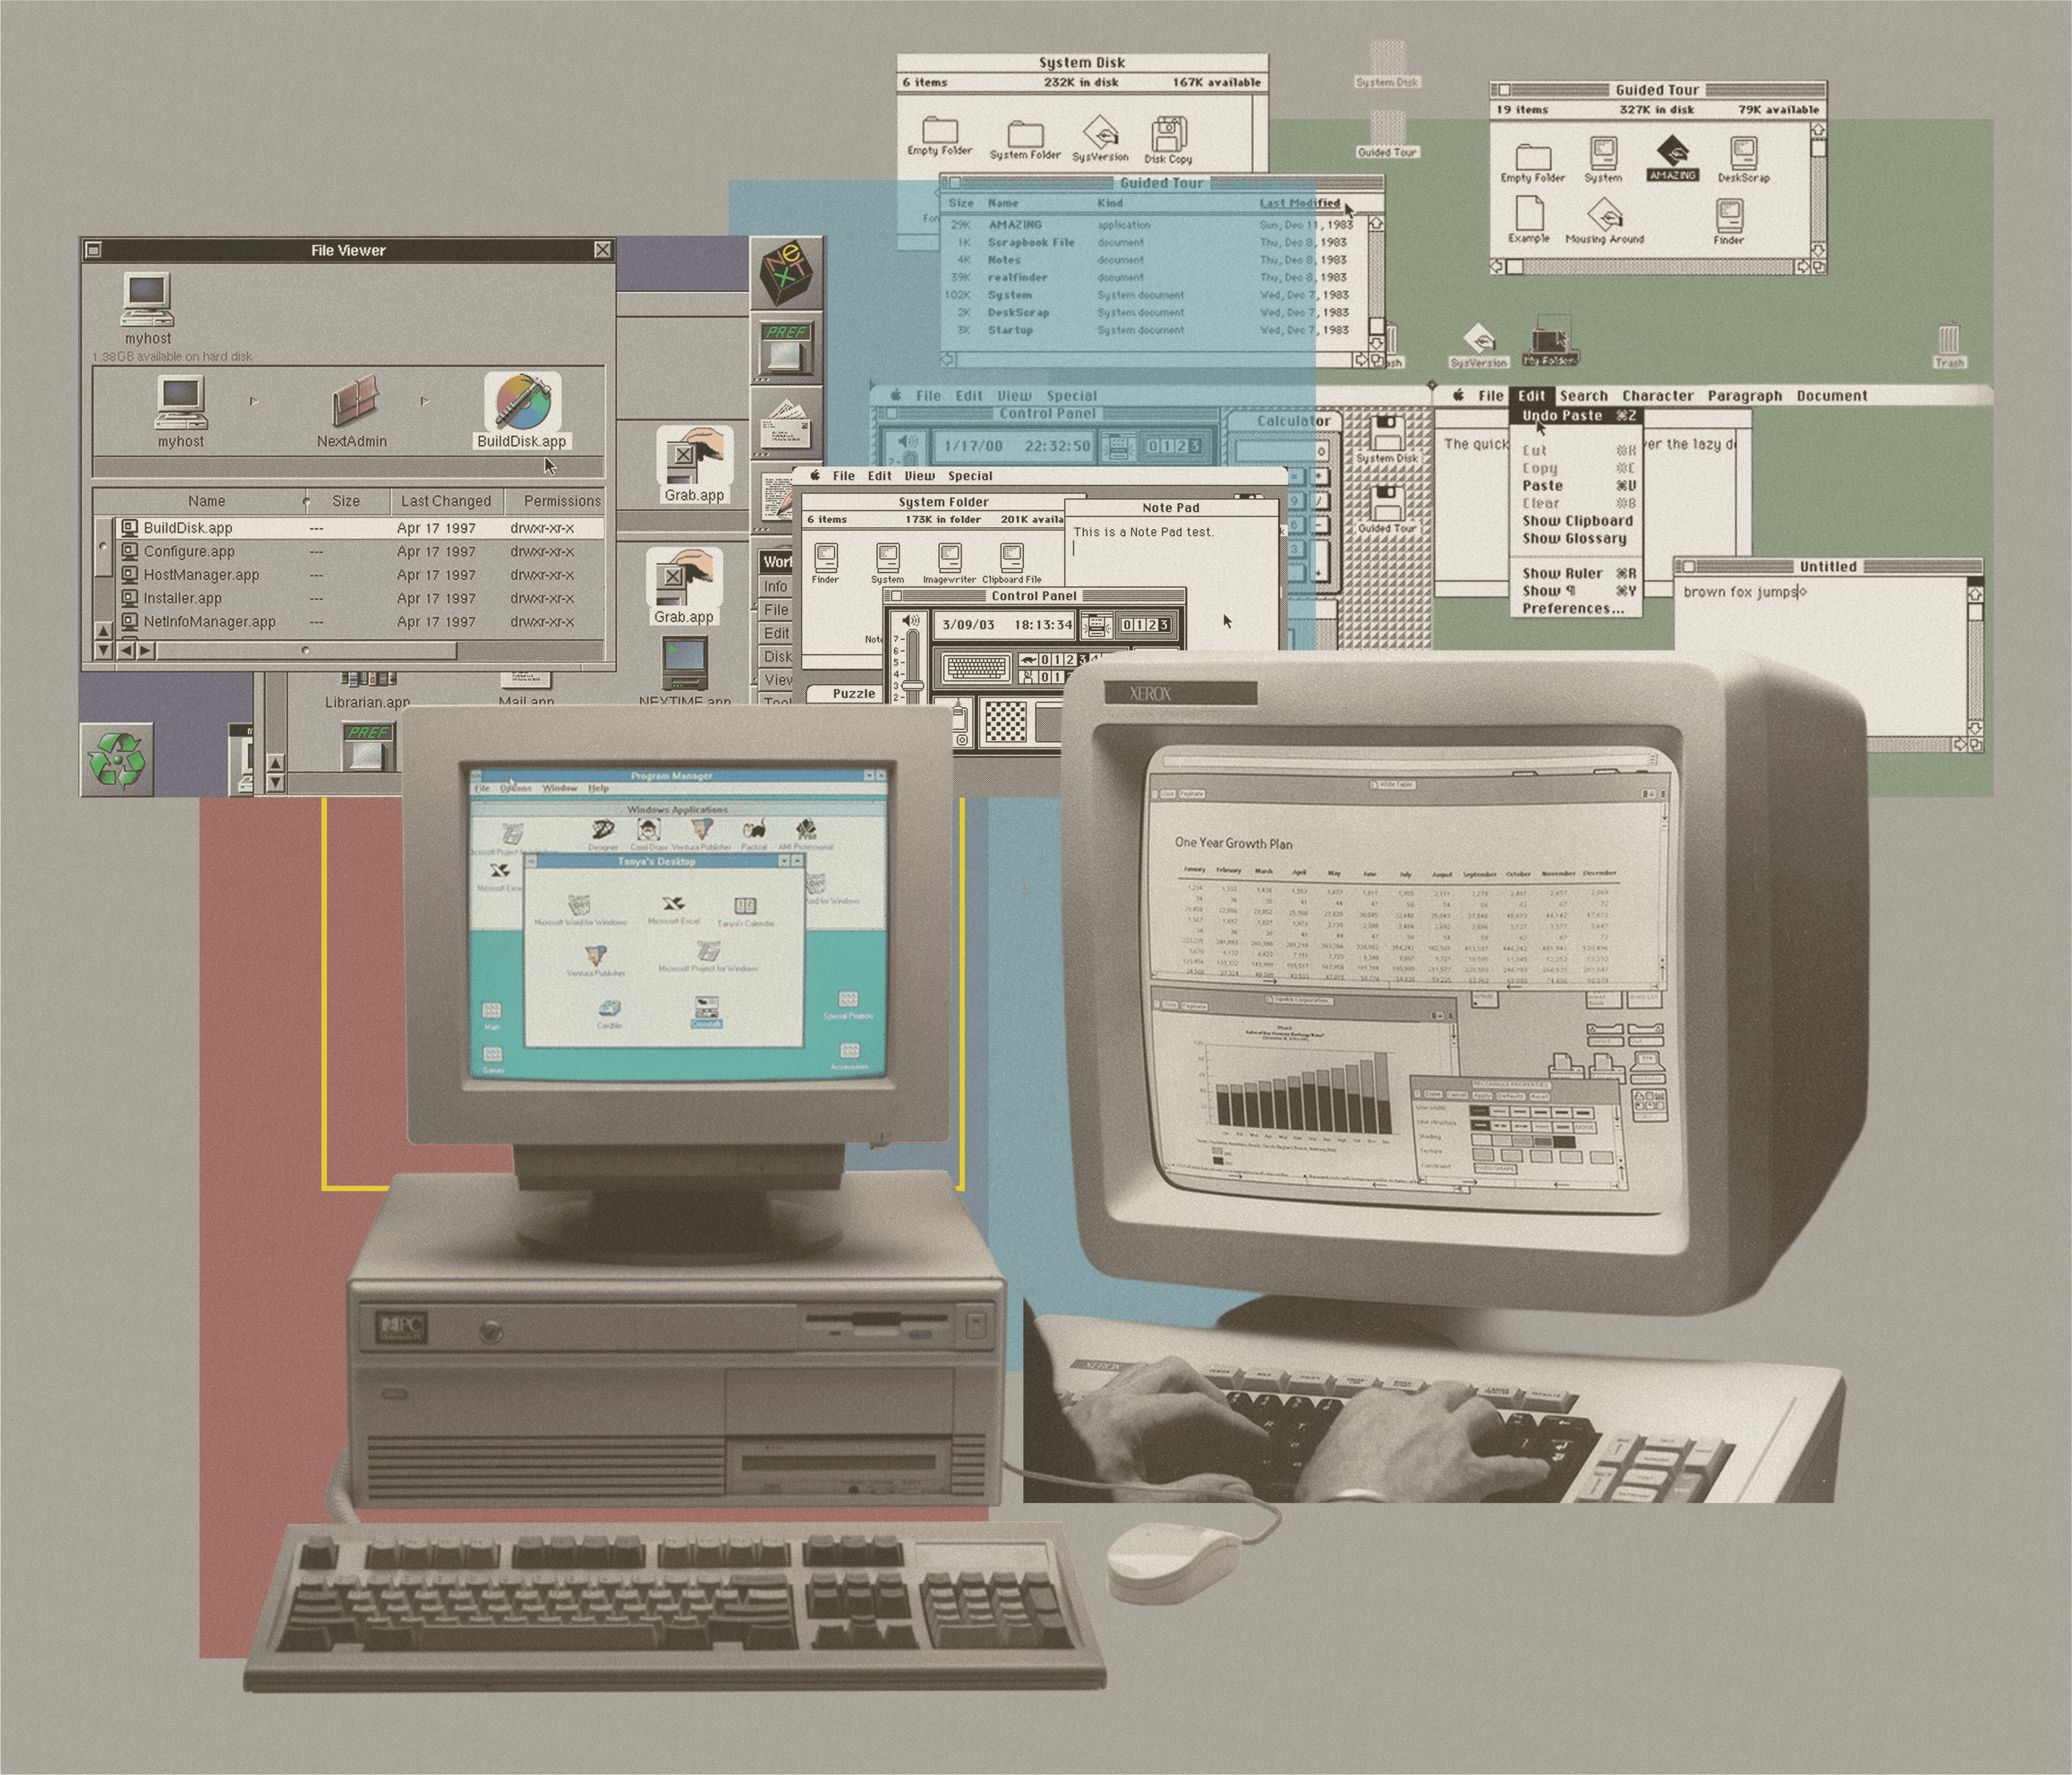
You still scan a grid of icons, hunt for the right app, and shape what you want around whatever the system expects.
That kept bothering me through my master’s program, and the more I looked into it the less it seemed like anybody was seriously trying to change it.
identifying the problem
Checking a flight time or making a calendar event means several manual steps across different apps, for something you could say out loud in four seconds.
That assumption also excludes people who aren’t especially technical, or who have cognitive or physical disabilities. And it scatters a single task across tools that mostly do the same thing, half of them behind a subscription you have to evaluate before you can even start.
None of this is new, and none of it has been solved. Nothing available today closes the distance between saying what you want and getting it.
Genie explores how Generative AI and multi-agent systems can translate user input into interfaces.
the solution
Creating Genie
Genie reimagines the home screen as something that assembles itself. You say what you need in plain language and it builds an interface around that. Below is how the system works, then the two deliverables.
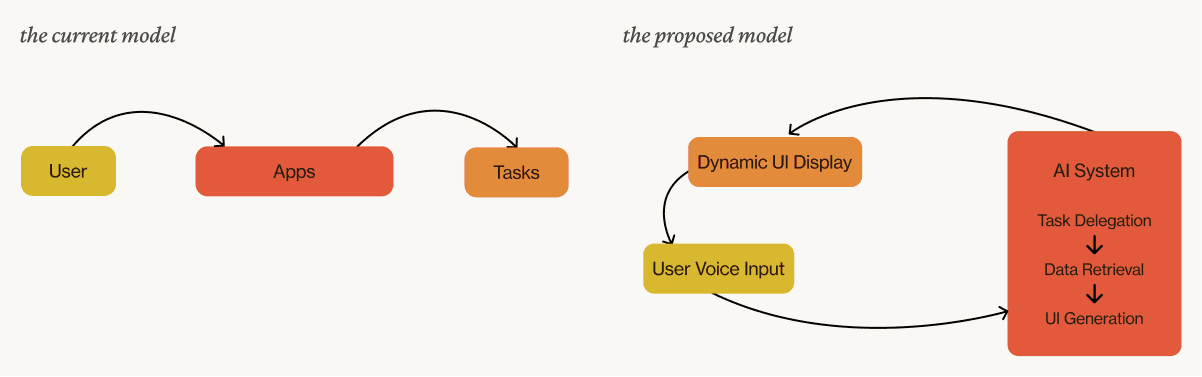
how it works
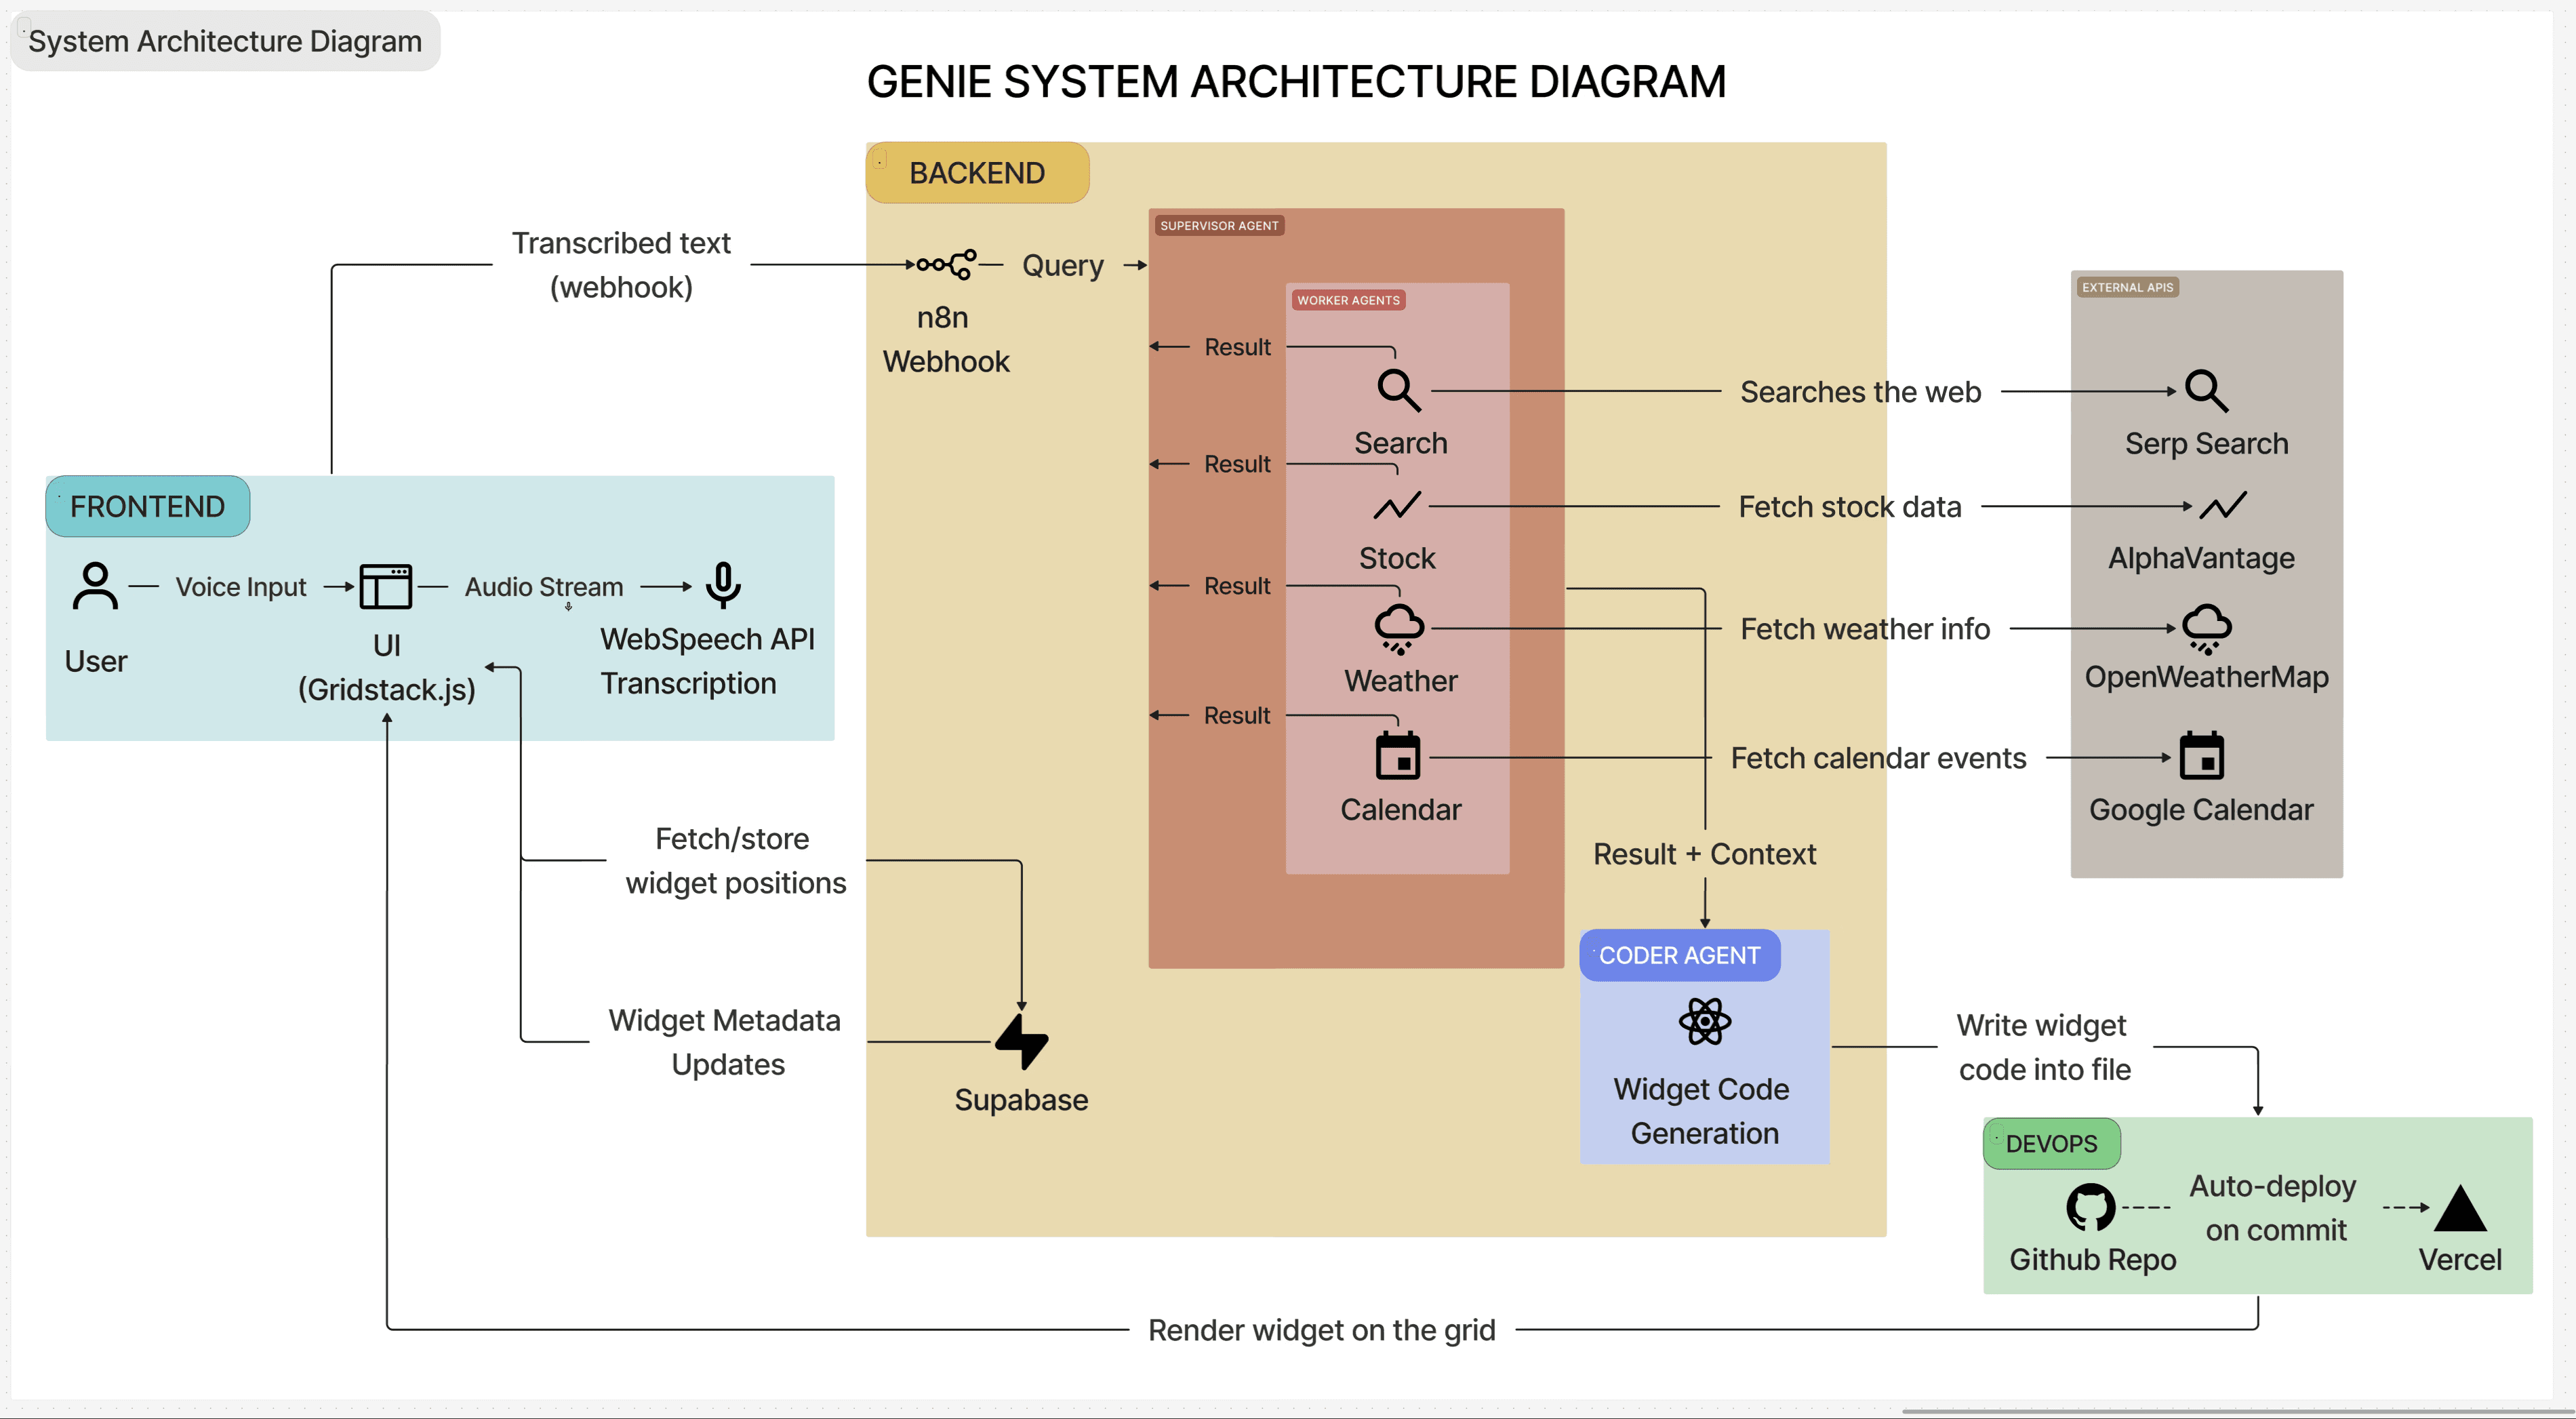
A central Supervisor coordinates specialised Worker agents. Three components carry the system:
01
Supervisor
GPT-4o parses intent, holds conversational memory, delegates.
02
Workers
Weather, Stocks, Calendar. Call APIs, return structured JSON.
03
Coder
Turns that JSON into working React components.
The orchestration lives in n8n, whose node editor keeps the logic visible and quick to change.
the probable future, a working prototype
The first deliverable had to run on technology that exists now. It answers one question: can an interface assemble itself around what you ask for?
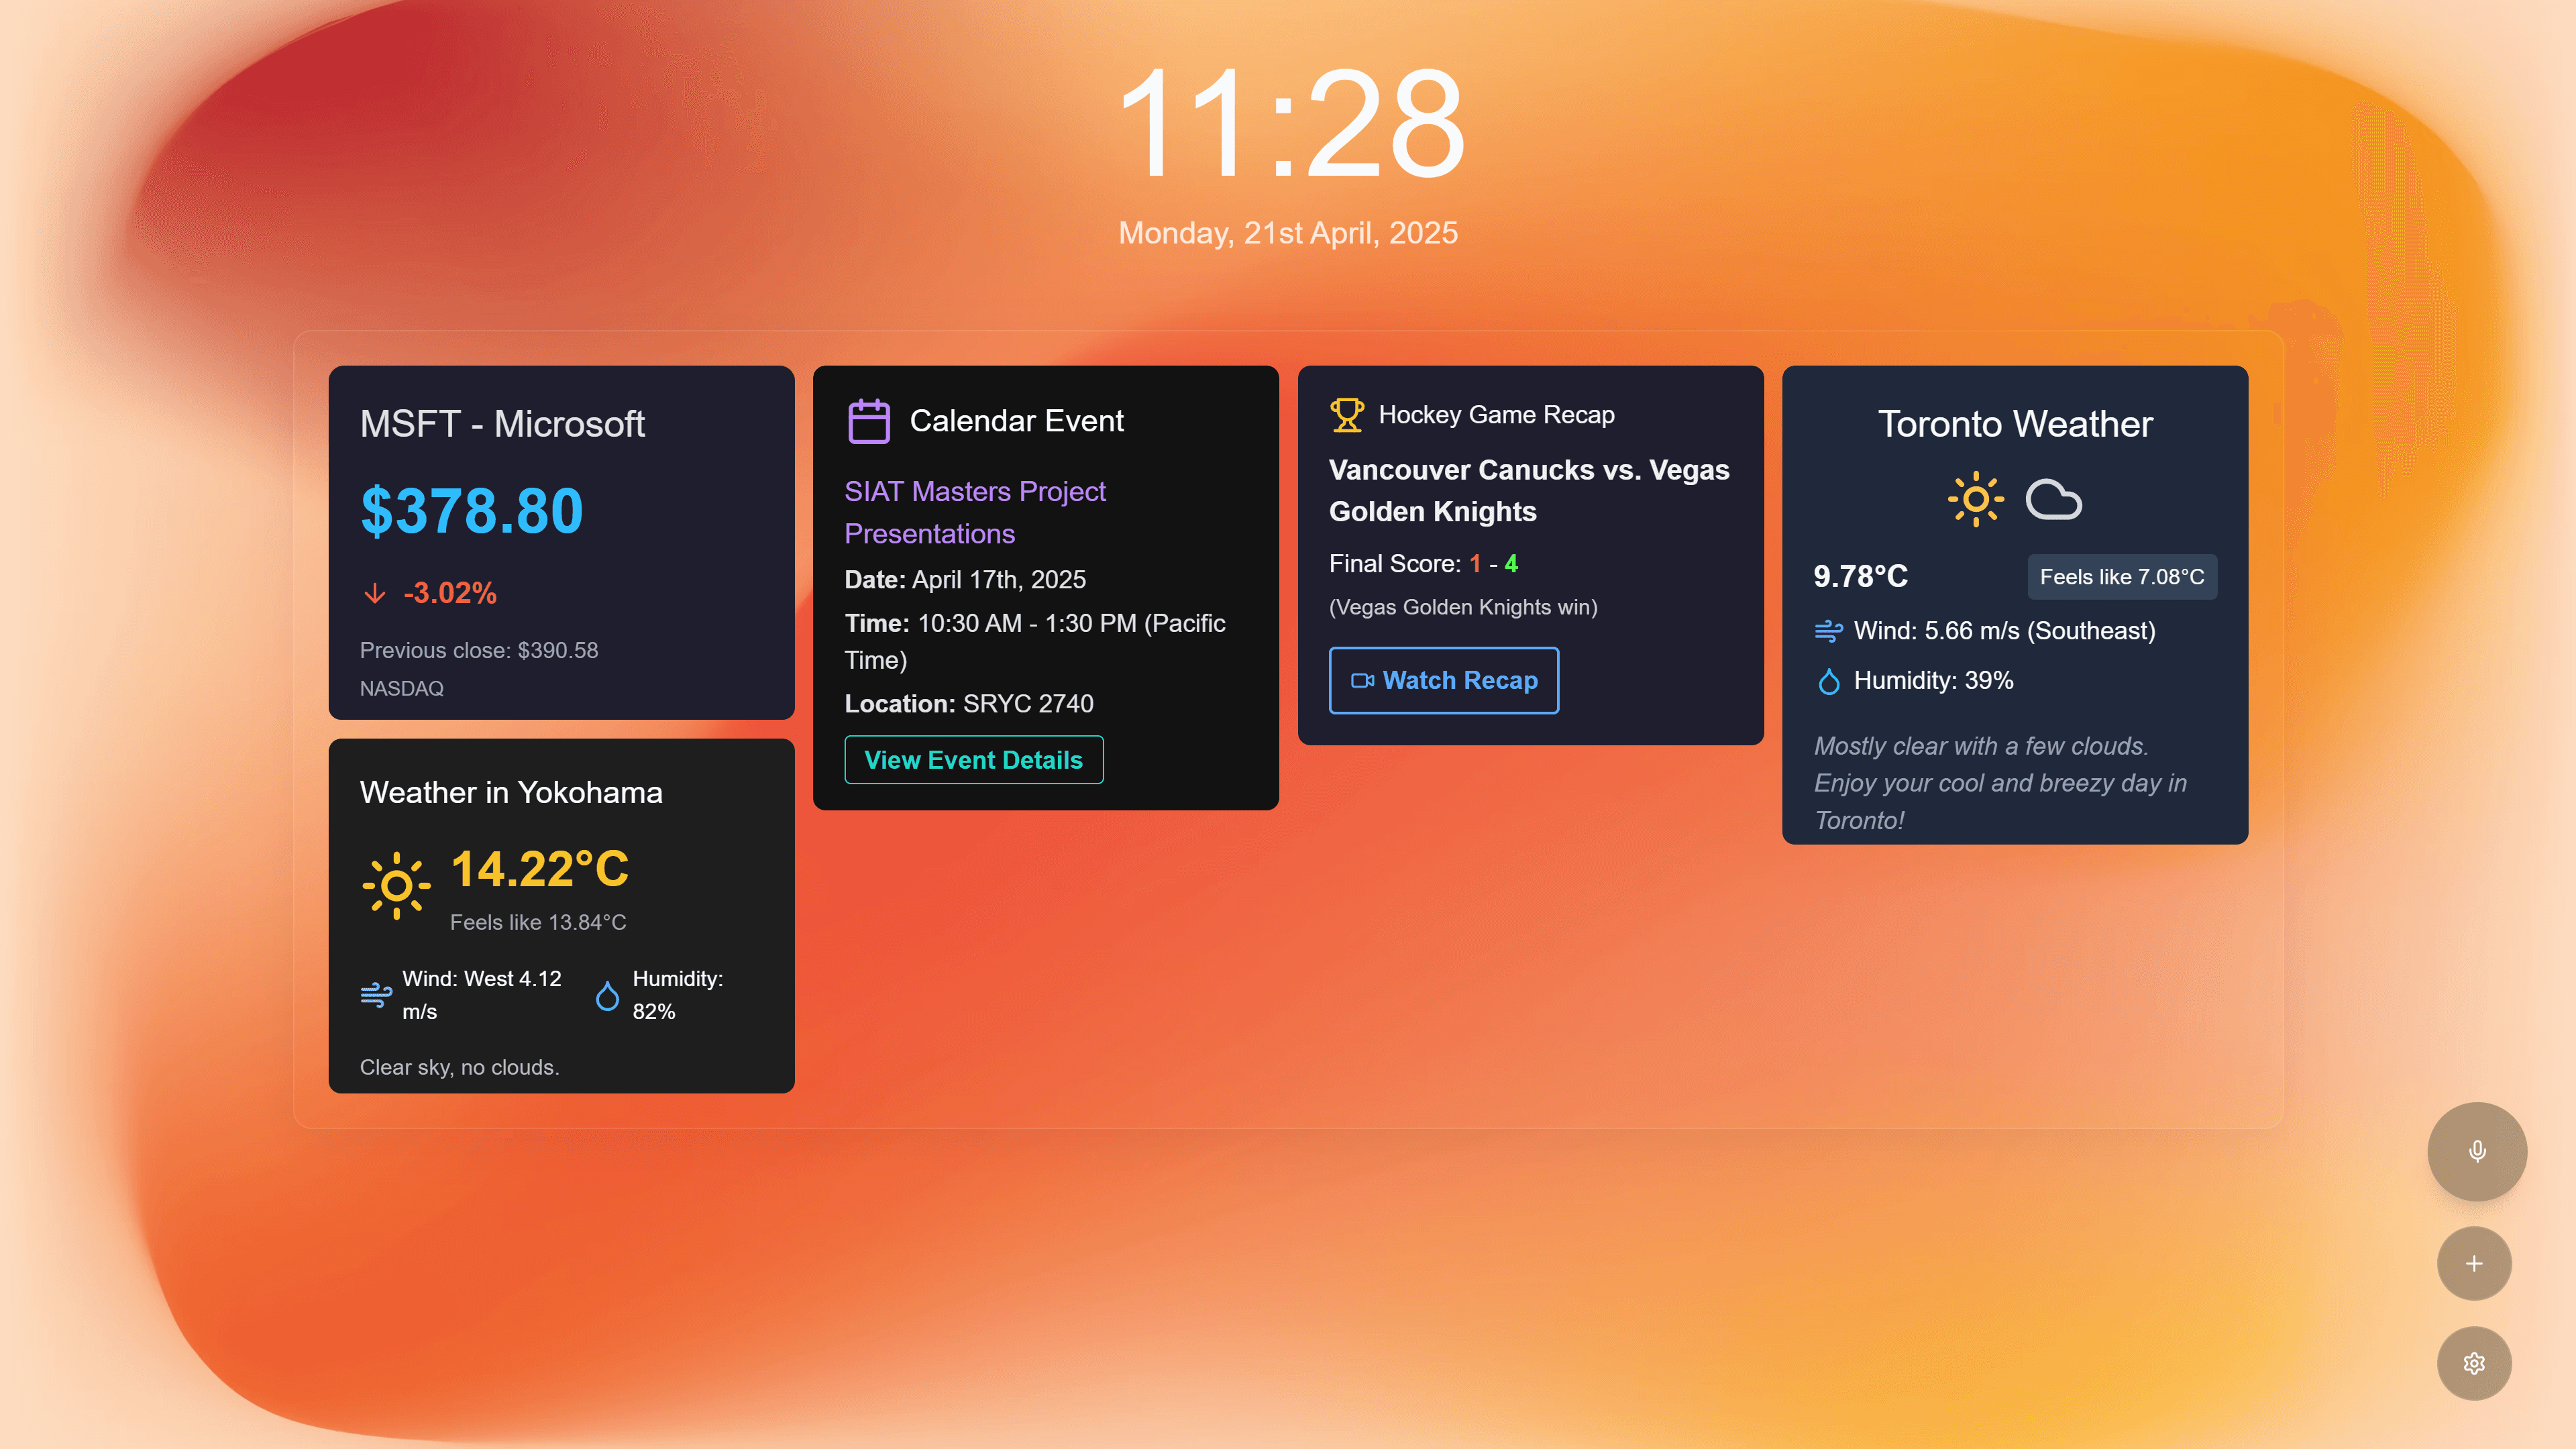
It can. Ask for the weather in Vancouver and a weather widget appears. Ask about a stock and you get a live card with real data. Ask for your next calendar event and it surfaces. No app, no navigation, no setup.
The interaction generates rather than retrieves. Watching it work the first time, rough as it was, told me the shift is technically possible today.
the preferred future, a design fiction
Latency and today’s models cap how good the prototype can feel. So the second deliverable drops those constraints: a video showing Genie in a future where generation is instant.
Following Dunne and Raby, the video works as a provocation rather than a demo. It asks what generative interfaces would mean for how we live with our devices, not whether we can build them.
the process
first, was this worth chasing?
Three things had shifted at once. Multi-agent systems moved development from coding toward orchestration (Li et al., 2024), and agents were already collaborating to produce coherent UI prototypes (Yuan et al., 2024). Meanwhile LLMs were finally getting past the failures that sank early voice interfaces (Corbett & Weber, 2016; Myers et al., 2018). Which gave me the opening:
LLMs provide the reasoning, agents provide the structure and lowers the barrier to get what you ask for.
so how do you design for the future?
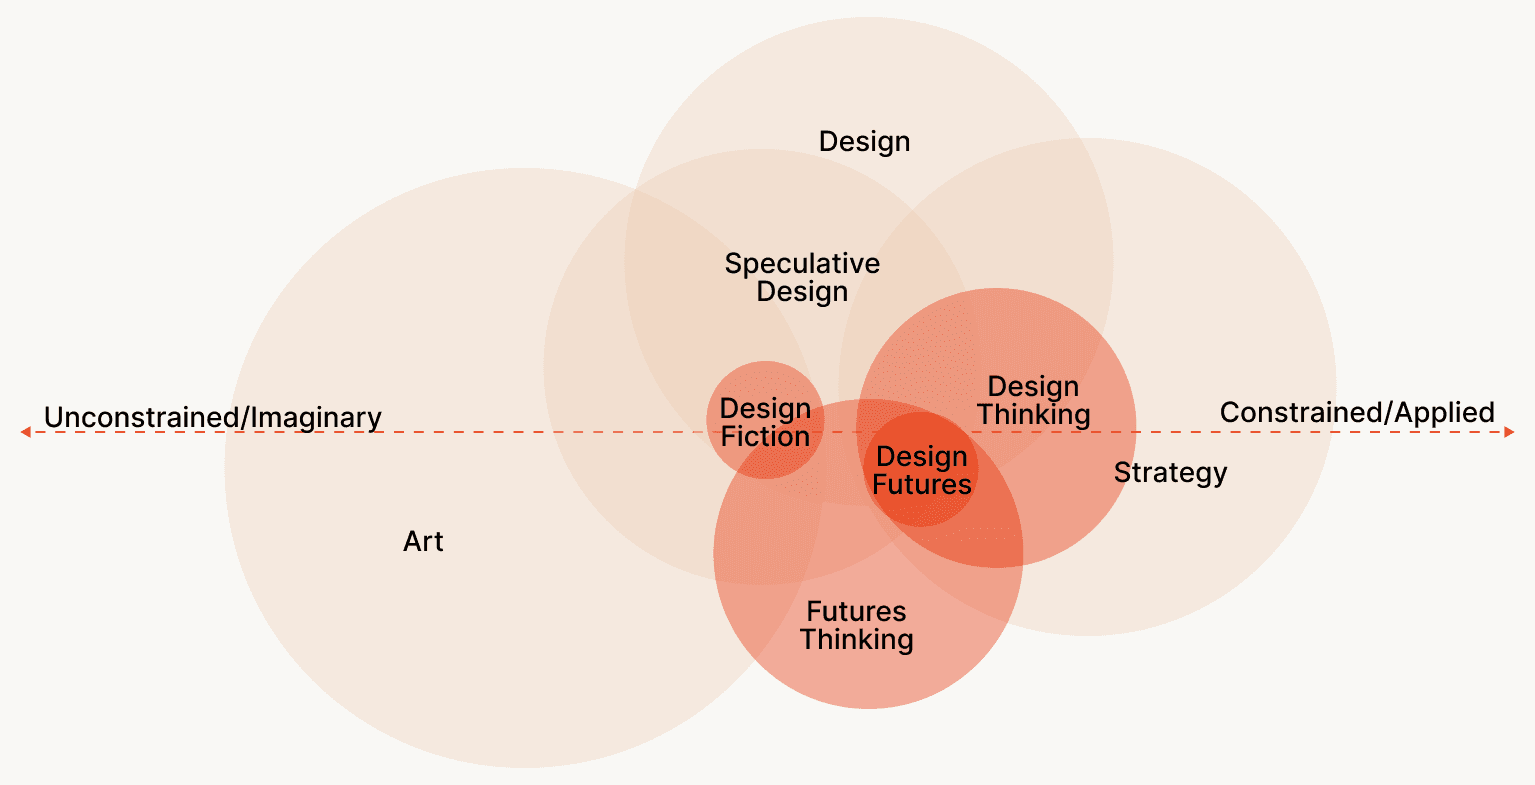
Speculative design methods, mapped from unconstrained to applied. Adapted from Elliott P. Montgomery’s “An Unresolved Mapping of Speculative Design”.
Design Futures sits near the applied end, a mix of design thinking and futures thinking. Design Fiction sits closer to the imaginary end. Together they gave me grounded speculation and a way to show what the result would look like in the near future.
design futures
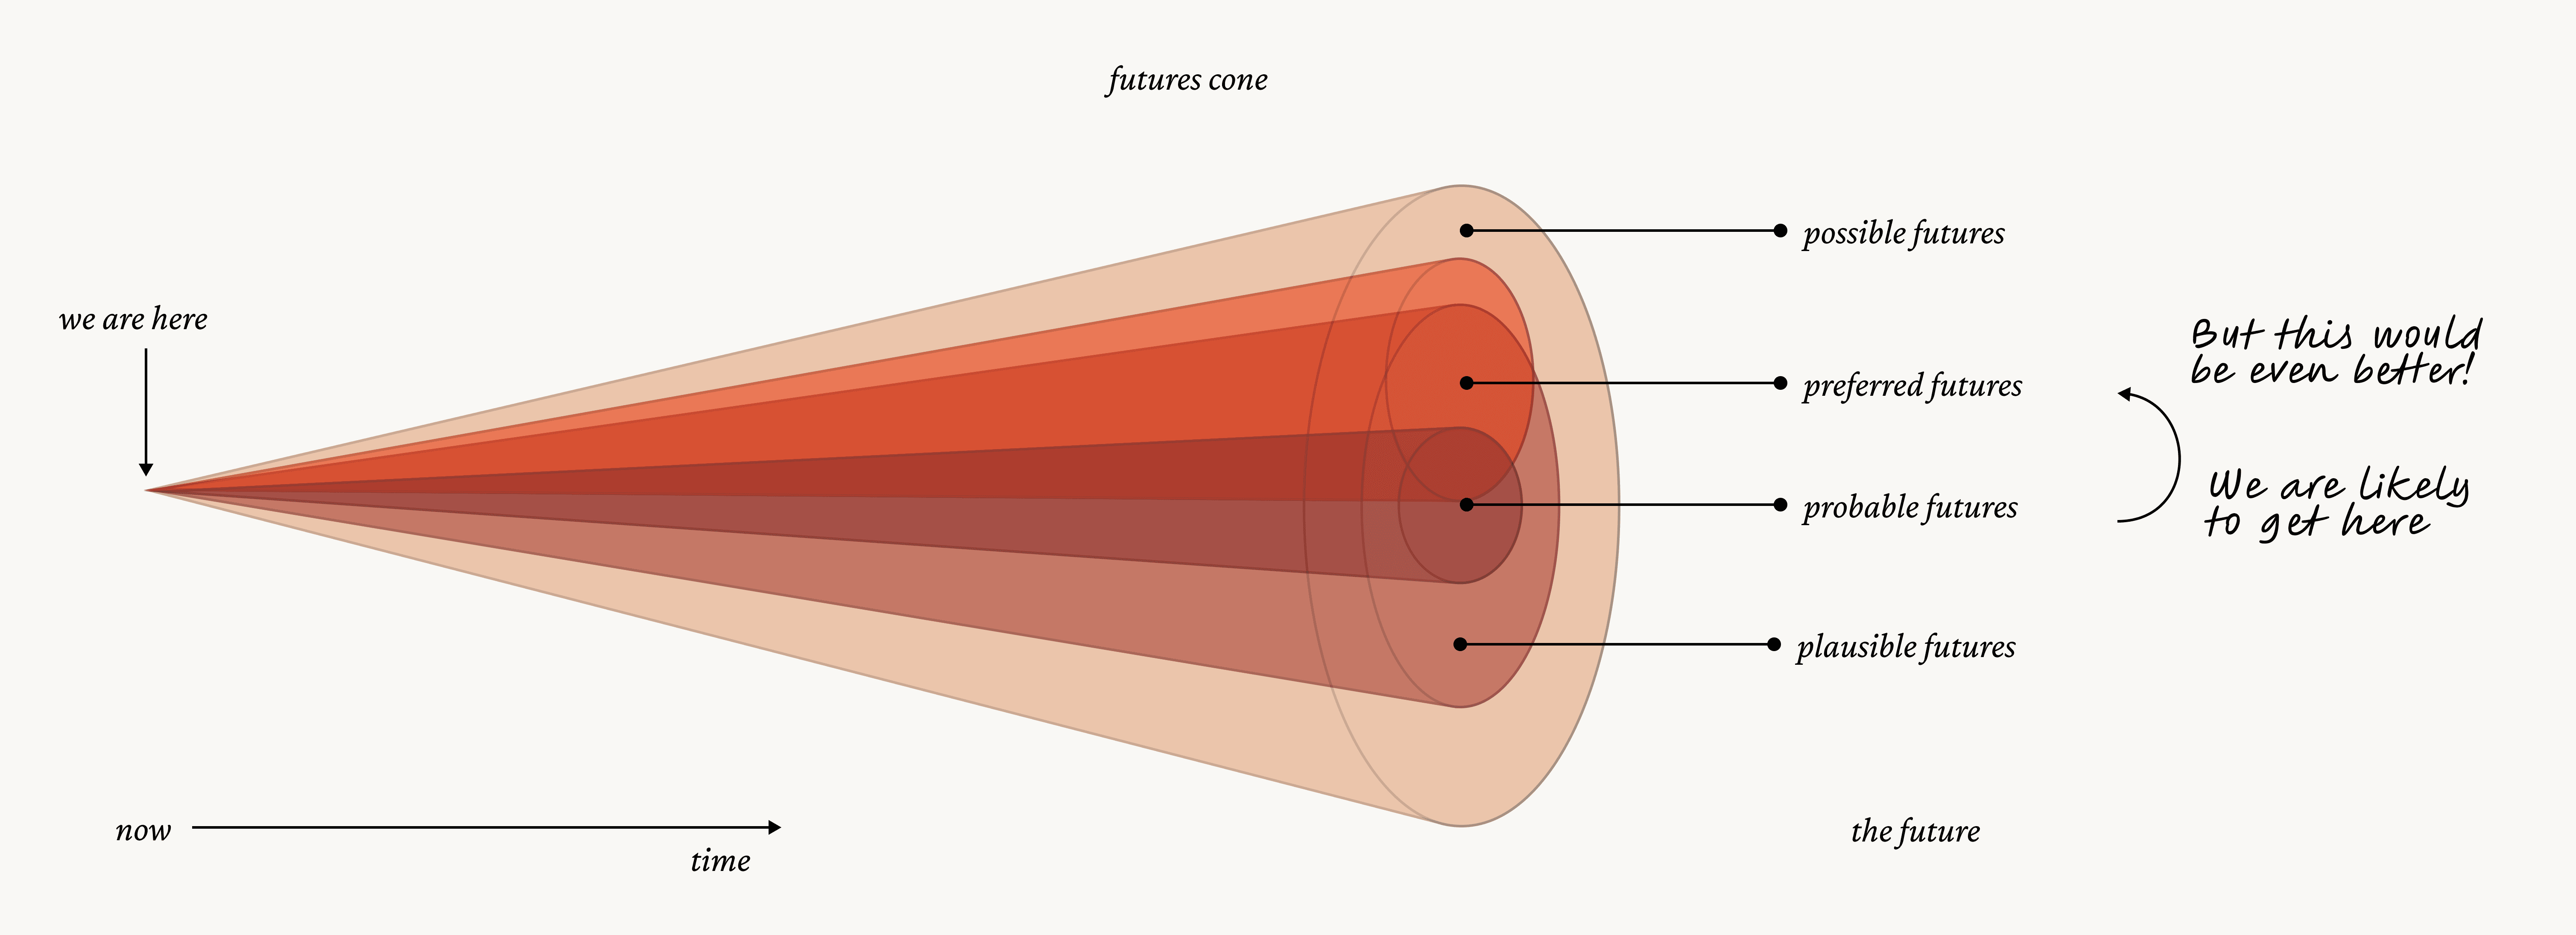
A modified version of the “Future Cone” adapted from Hancock and Bezold (1994).
Design Futures sits between Design Thinking’s rigour and Futures Thinking’s long view. It works by naming drivers, the forces already reshaping a field, and signals, the early evidence of where they lead. My two drivers:
DRIVER 01
Generative AI
Moving from generating content to generating functional interfaces.
DRIVER 02
Multi-agent systems
Frameworks that let agents split & sequence work without humans directing.
The signals were already public. Vercel’s v0 generated functional UIs from text. Microsoft’s AutoGen and Google’s agent frameworks showed AI systems solving problems together. That pointed at two futures worth designing for:
PREFERRED
What it should become

design fiction
Design Futures told me where to aim. Building only inside today’s limits would have undersold where the technology is going.
So following Dunne and Raby’s Speculative Everything, I built a diegetic prototype, what David Kirby calls a prototype that lives inside a fictional narrative.
The vision video puts Genie in a plausible future ecosystem, the way Apple’s 1987 Knowledge Navigator let people picture computing long before the hardware caught up.
then I tried to break my own idea
My supervisor runs an exercise called 5 Intelligent Failures: stress-test the core assumptions before production code. I split the project into its five parts, the agentic framework, voice input, prompt engineering, frontend, and backend, and wrote failure scenarios for each, such as users not trusting voice or agents picking the wrong widget. I tested them through sketches, mockups and small code experiments, with peers giving informal feedback. There was no formal usability study.
what survived became the architecture
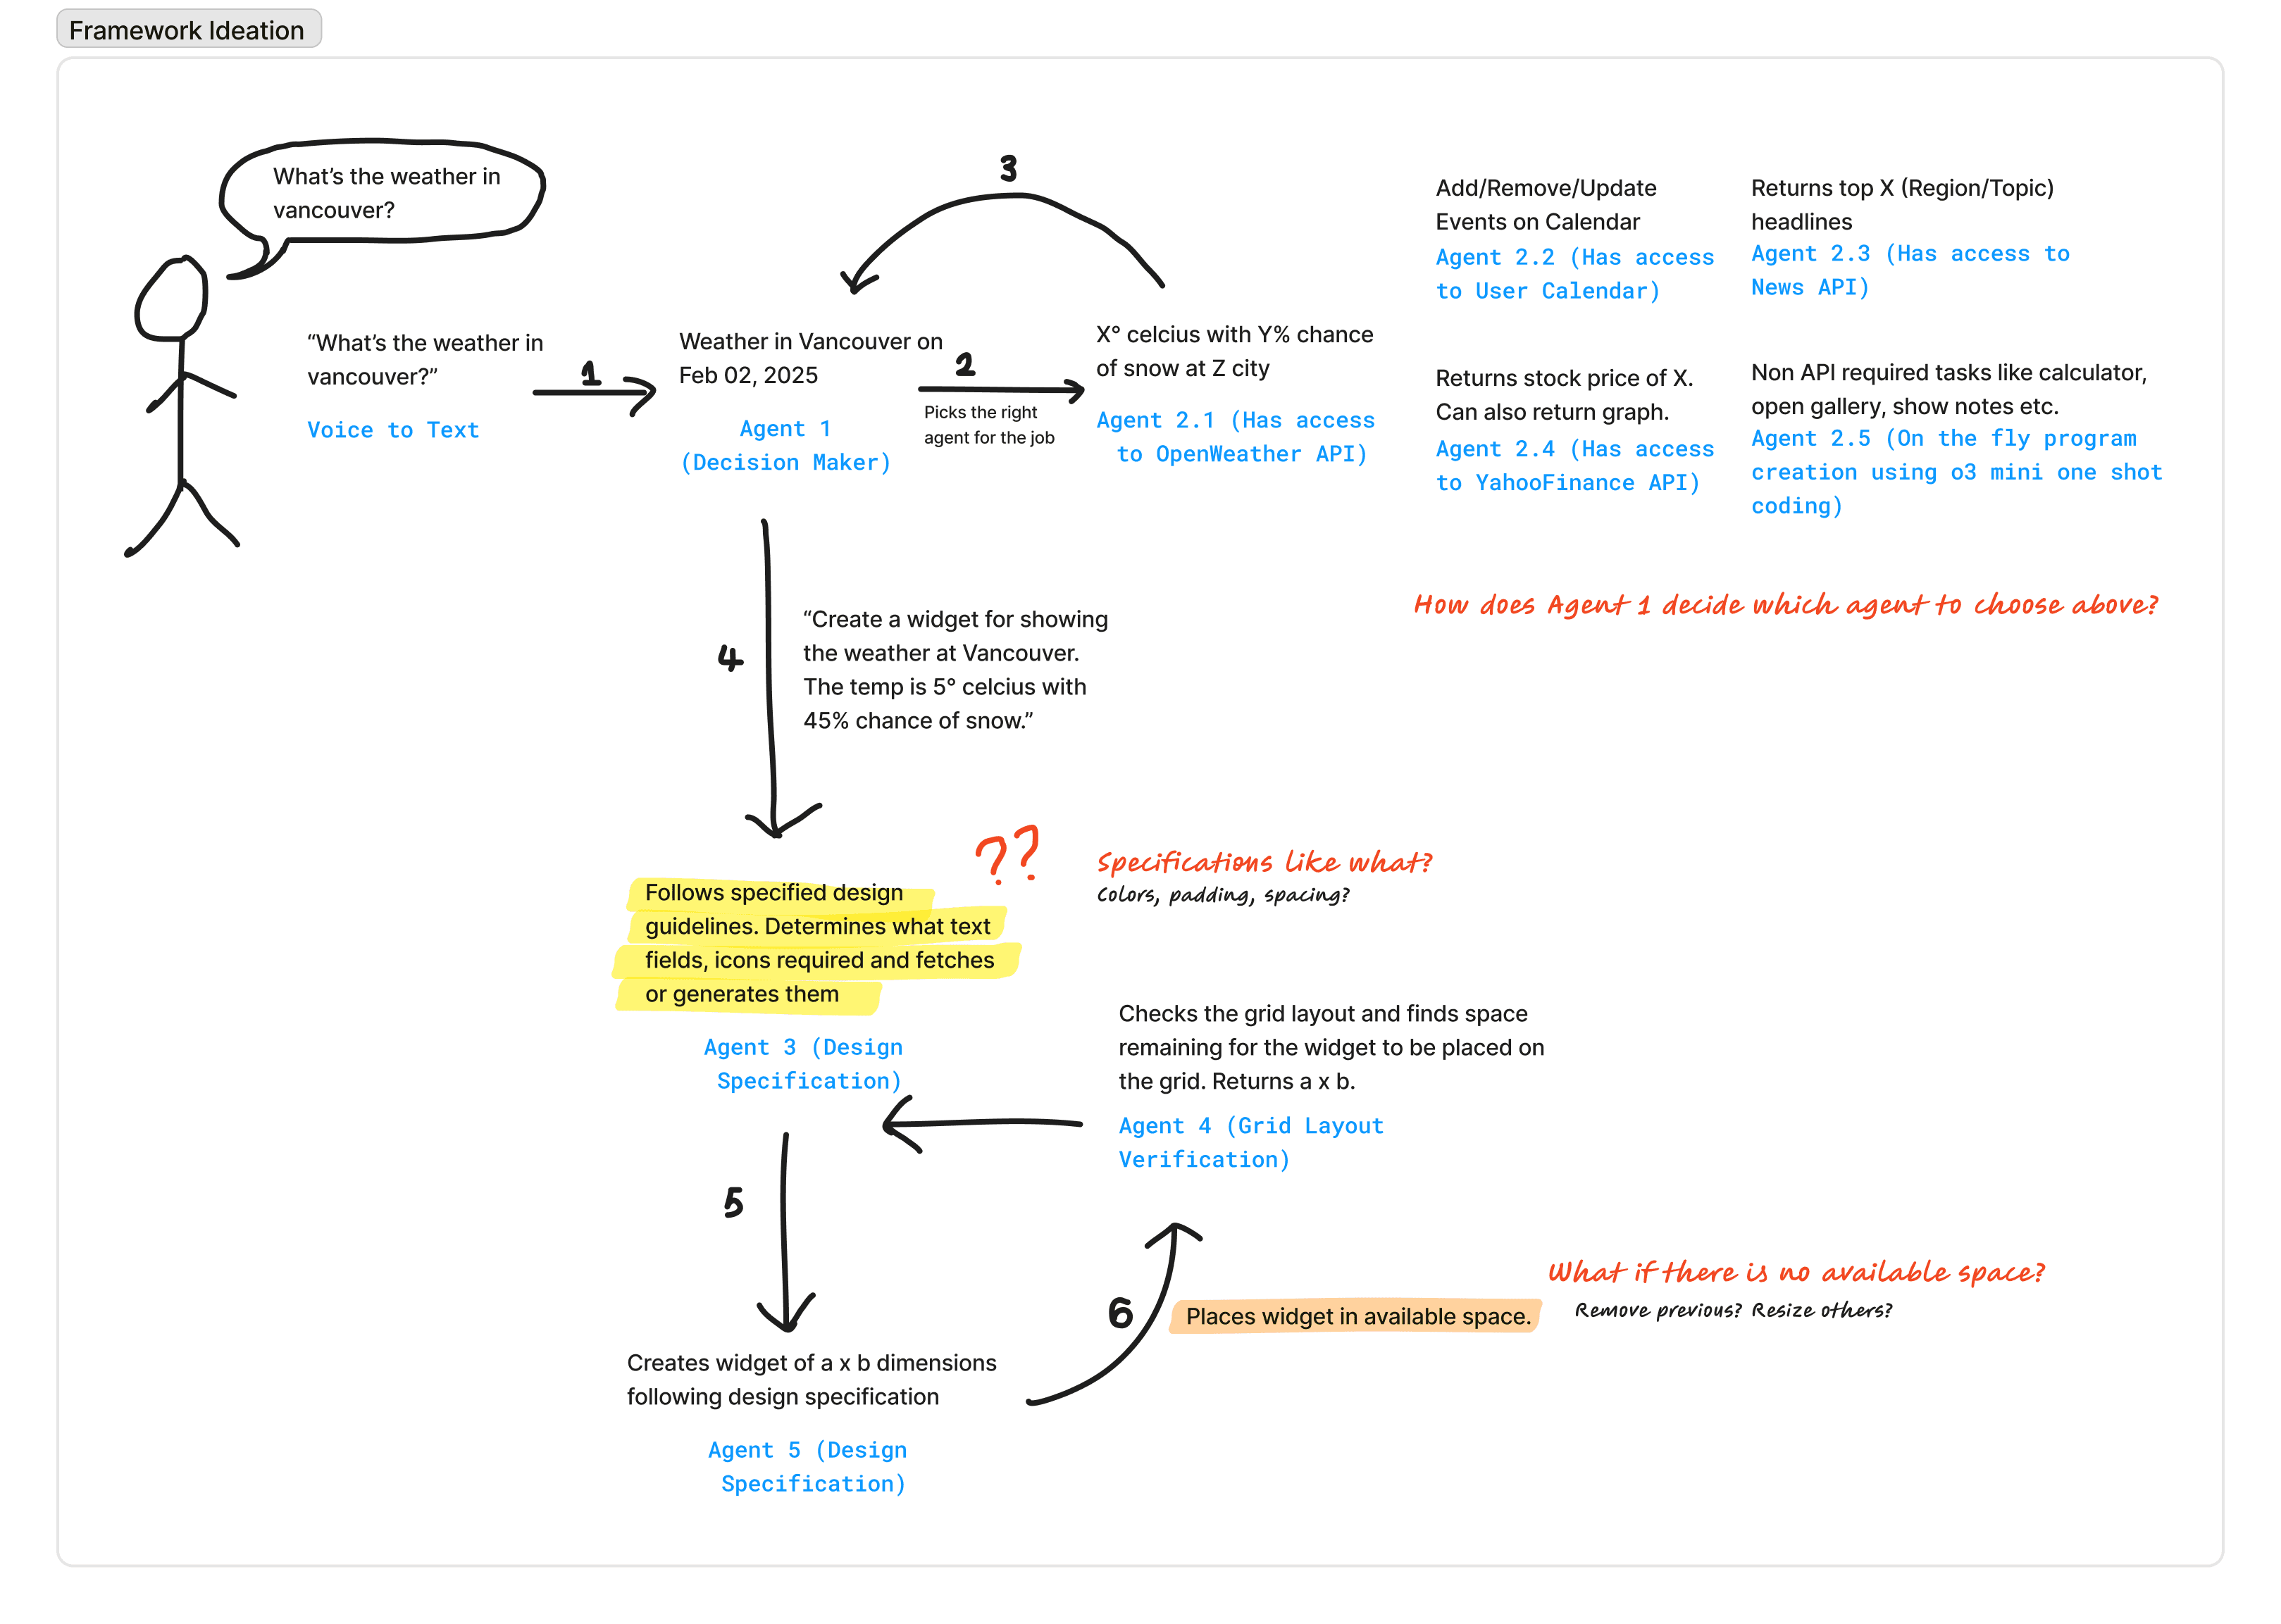
Three components came out of it:
A Supervisor Agent to read intent and delegate.
Worker Agents to pull data from public APIs.
A UI generation step to turn that data into components.
cheap tests before expensive code
tldraw sketches that explored layout and interaction states (how a generated UI collapses, expands, or hands control back to the user)
n8n workflow prototypes that encoded voice → action sequences.
The tldraw frames checked the architecture logic. The n8n prototypes checked layout affordances, voice-to-intent parsing, worker sequencing, and the JSON shape the frontend would consume. Both cut risk before I committed to the stack.


building it
n8n for agent coordination, OpenAI for language understanding, Supabase for storage, React for the generated components.

n8n
Agent orchestration, LangChain JS

Supabase
Postgres, widget metadata
OpenAI
o3-mini and 4o

React
Widget rendering
frontend
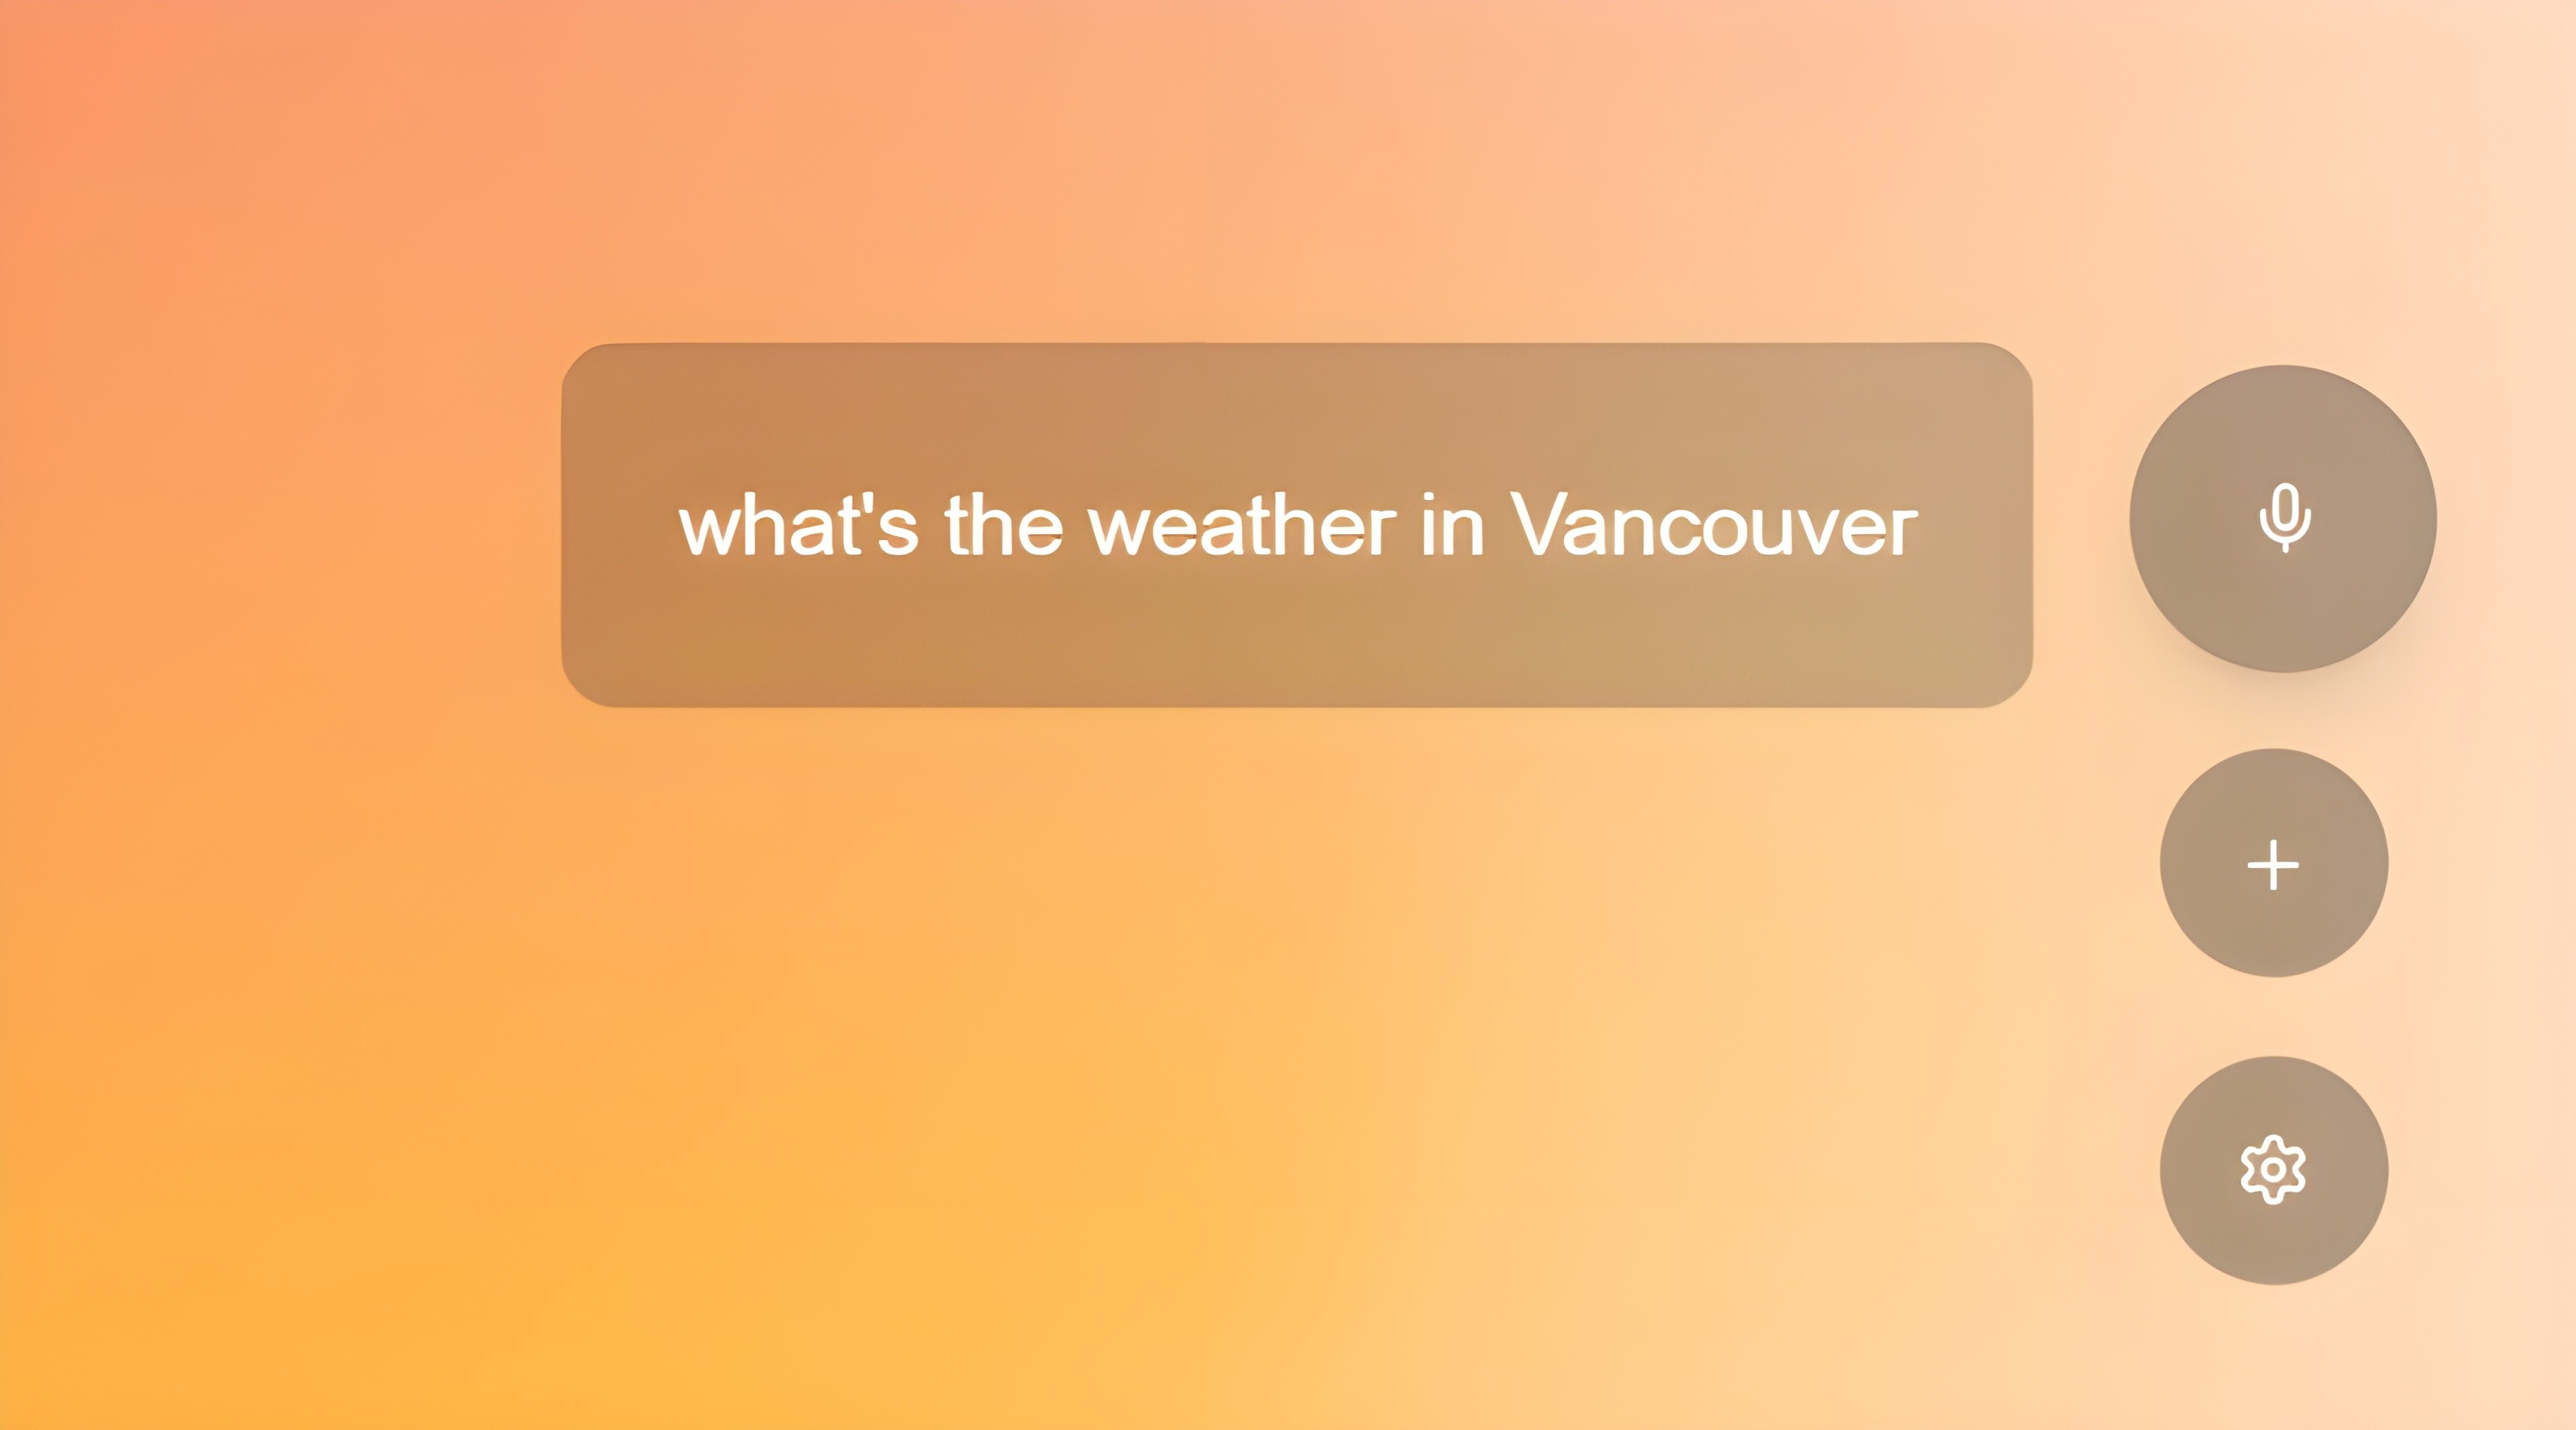
React with the WebSpeech API, transcribing as you speak so the system responds before you finish the sentence. The final transcription goes to n8n by webhook.
The interface stays deliberately plain, a dashboard with a central clock, closer to a home screen than an app. GridStack.js handles layout and drag-and-drop, and Supabase keeps widget positions between sessions.
backend
The Supervisor workflow takes the parsed voice input and decides which Workers to activate. A travel request might trigger Calendar, Flight Search, and Weather in sequence.
Time constrained how many Workers I finished. Three shipped:
Calendar Agent
Google Calendar API
Stock Agent
Alpha Vantage API
Weather Agent
OpenWeatherMap API

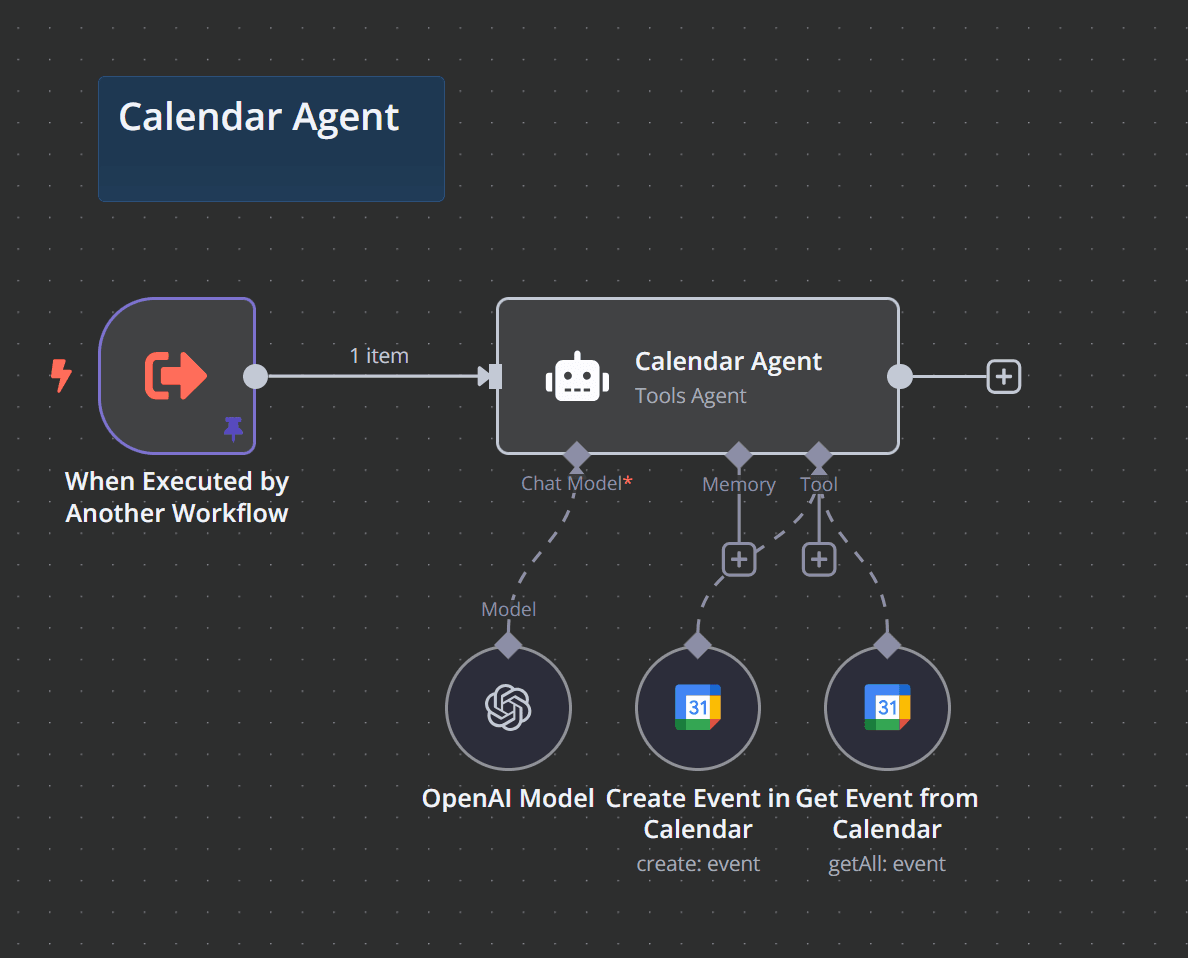


The Coder Agent then takes the structured output and writes the React widget, using Lucide icons and Tailwind so the results stay visually consistent. Finished components commit to GitHub, which triggers the frontend update.
what didn’t work
Latency is the honest limitation. A widget took 15 to 40 seconds to appear, which is a long wait next to tapping an icon. Parallel agents, faster APIs and clear loading states would close some of that gap.
LLMs write functional code, but holding their output to a style guide took constant manual correction. That’s where the next iteration goes.
Shipping widgets by committing generated code to GitHub and loading it into the frontend worked, but it was an unconventional and inefficient pipeline that made deployment and maintenance harder. Sending generated widget data straight from the backend to the renderer would be the cleaner route.
The goal was never a finished product. It was to show the shift is ready, and what it might feel like.
Genie is one attempt at that. The home screen has looked the same for forty years. It doesn’t have to look the same for the next forty.
Sources:
Corbett, E., & Weber, A. (2016, September). What can I say? addressing user experience challenges of a mobile voice user interface for accessibility. In Proceedings of the 18th international conference on human-computer interaction with mobile devices and services (pp. 72-82).
Dunne, A., & Raby, F. (2013). Speculative everything: Design, fiction, and Social Dreaming. The MIT Press.
Hancock, T., & Bezold, C. (1994, March). Possible futures, preferable futures. In The Healthcare Forum Journal (Vol. 37, No. 2, pp. 23-29).
Kirby, D. A. (2011). Lab coats in Hollywood: Science, scientists, and cinema. Mit Press.
Li, X., Wang, S., Zeng, S., Wu, Y., & Yang, Y. (2024). A survey on LLM-based multi-agent systems: workflow, infrastructure, and challenges. Vicinagearth, 1(1), 9.
Myers, C., Furqan, A., Nebolsky, J., Caro, K., & Zhu, J. (2018, April). Patterns for how users overcome obstacles in voice user interfaces. In Proceedings of the 2018 CHI conference on human factors in computing systems (pp. 1-7).
Yuan, M., Chen, J., & Quigley, A. (2024a). MAxPrototyper: A Multi-Agent Generation System for Interactive User Interface Prototyping. arXiv preprint arXiv:2405.07131.